
You cannot deny every tool and still ship

Product wants the patch before standup. Security wants a gateway that can say no. I have sat between them. Both are right until someone makes it one dial.

Deny every tool and the agent is a chatbot. I have watched engineers stop waiting. They open the IDE on the laptop, shell still on, kubeconfig still in the environment, and they ship from there. Your deny rate looks perfect. Nobody complains. That quiet is the part that gets me. The control did not win. The work left.
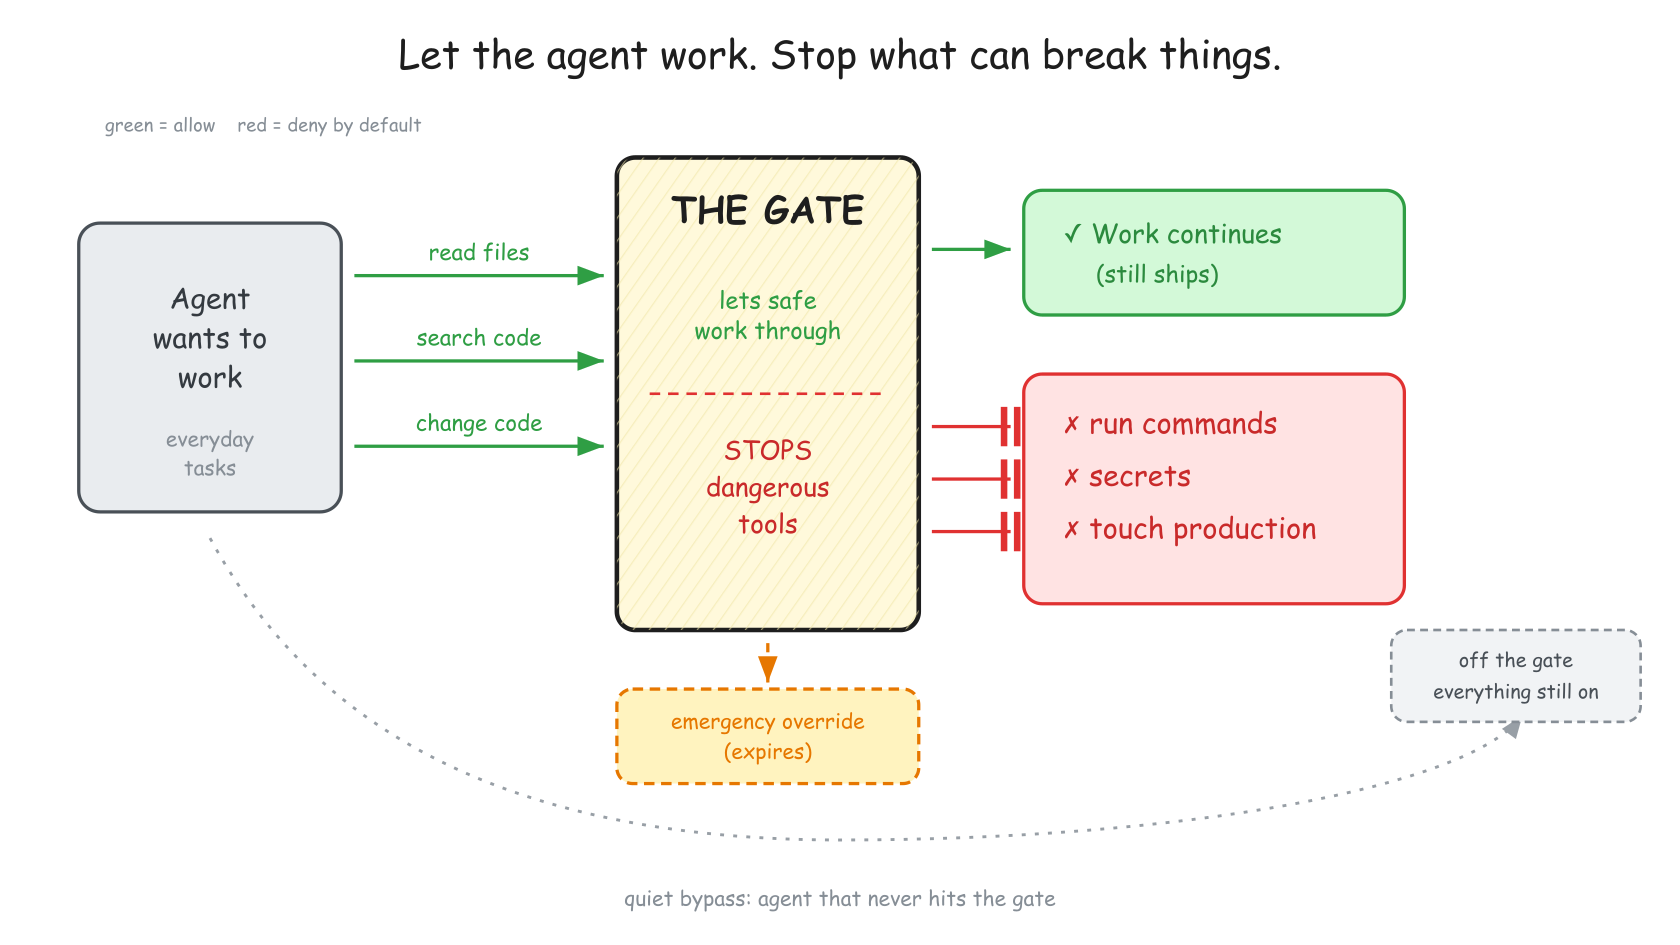
Diagram: an agent sends read files, search code, and change code through a gate that lets safe work continue, while run commands, secrets, and touch production are stopped by default. A dashed emergency override expires. A dotted quiet bypass goes around the gate where everything is still on.

Same argument without the table. Let the everyday work through. Fail closed on the three that can ruin your week. Any override dies on a clock. And go find the agent that never hits the gate.

Allow the shell because the tests will not run, and you handed a confused deputy a production write. I already wrote that one up: when your bot becomes the payload. This is the deal I will defend when both sides are in the room.

You cannot deny every tool and still ship. Sort them by what they can break. Shell, secrets, and prod write fail closed. Read stays. A write that can only touch the PR branch stays. Take those away and you do not have a PR agent. You have a linter with opinions.

Agent-on-agent: when your bot becomes the payload

You ship an outer agent that plans. It spawns a "helpful" inner agent to dig, summarize, or call tools. Product demo looks clean. Trust model does not: classic confused deputy, just with LLMs.

The inner agent is often the one with broader tools, longer memory, or the system prompt that names secrets and schemas. Untrusted content does not need to jailbreak the outer model. It only needs to steer the inner one into echoing what it already knows, or calling a tool the outer agent would never have been allowed to call.

Your nested helper can become the payload. Prompt leak. Tool/schema leak. Same family of failure as approving an MCP server once and hoping every later tools/call is fine (MCP gateways).

Access requests belong where the team already works

Most access request "systems" are a scavenger hunt. Ticket portal for some tools. Slack DM for others. A spreadsheet for the weird ones. Someone with admin rights eventually clicks Approve in a console you do not have. The requester waits. The approver forgets. Onboarding docs live somewhere else.

The worst option is the DM. Access granted in a private DM leaves almost no trail. No clear record of when it was asked for, why it was needed, or who said yes. That is a time bomb for offboarding, incident response, compliance, and the 2am question: who has maintain on that repo?

The fix is not a prettier portal. Treat access request as a product lifecycle: catalog β†’ route β†’ grant β†’ onboard. Put that lifecycle where the team already works. For a lot of orgs that is Slack. For eng teams living in GitHub, Issues can be the same product with a different skin.

What GuardDuty AI Protection actually detects (and what it doesn't)

AWS shipped GuardDuty AI Protection as GA in mid-July 2026. If you already run Bedrock or SageMaker AI and GuardDuty, this is the protection plan that finally looks at model invocation data events instead of only management-plane noise.

It is not "AI security done." It is a specific data-source plan with three finding types. Know what it watches, how to turn it on, and what to do when Low severity findings show up. Then know what it will never see.

MicroVM runners protect the host. Your supply chain still runs inside the job.

Teams buy Firecracker-/Kata-backed runners (or DIY) and talk like the CI supply chain problem is closed. Hardware isolation. Fresh VM per job. Tear it down. The vendor deck lands. The budget conversation moves on.

A microVM protects your host from the job. You still have to protect the job from the supply chain.

MCP this, MCP that. Attack surface, gateways, and cMCP.

Your engineering, infra, or security team is wiring agents to tools inside real environments: GitHub, Stripe, Slack, cloud APIs, filesystem servers, whatever the agent needs to act. Same session. Fine.

The quieter question is MCP gateway security: once those tools are reachable, who is actually allowed to say no before the upstream runs?

An MCP security gateway sits between the agent client and upstream MCP servers. It evaluates each tools/call against policy (allow or deny), keeps an audit trail, and optionally attests that path in a TEE. Raw MCP is the protocol and the catalog. The gateway is the control plane that can refuse a specific call before credentials, files, or APIs get touched.

That is different from a dumb reverse proxy that only terminates TLS or multiplexes routes. Auth at the door is not authz on the tool. Approving an MCP server once is not the same as deciding whether read_file on .env should ever leave the client.

Runtime Trace attestation: signed image, dishonest process

The image signature said yes. Provenance said GitHub Actions on main. The image still shipped with a build that opened the wrong sockets and ran a binary nobody named in the workflow. That is not a signing-tool bug. That is a missing link in the chain of trust.

Eradicate long-lived tokens before they eradicate you

If you are still using classic GitHub PATs in your environments "just for pulling, read or packaging," you are not being pragmatic. You are accepting forever access as normal. That is a culture problem. Tooling only follows.

Your JetStream is fine. You just have two of them.

Publish returns ack. Consumer never sees the message. Restart a pod and a stuck queue suddenly drains. Realtime join works on one pod; another user never sees it. Websocket adapter events vanish depending on which replica you hit. Same cluster. Same Service DNS. Different JetStream stores. That is the smell.

AKS + Karpenter: kubectl logs returns 401 Unauthorized

kubectl get pods is fine. kubectl describe is fine. Then you hit kubectl logs on a pod that just landed on a Karpenter node and get 401 Unauthorized. Same cluster. Same context. Pods on the system pool still give you logs. That split is the smell.